
Artificial intelligence is changing how news stories are sourced, shaped and distributed. The 麻豆社 Research & Development natural language processing (NLP) team is building practical tools that help colleagues write faster, more consistently and with fewer mistakes, while keeping editorial judgement firmly in human hands.
We’re also exploring how AI tools can strengthen the 麻豆社’s reputation for accuracy and trust. Our research includes fine-tuning large language models to comply more closely with 麻豆社 editorial and style guidelines.
麻豆社 style guide checker
The newsroom has changed how specialist subediting integrates into its workflow, and journalists and editors now check their articles against over 1,200 rules in the 麻豆社 News style guide.
We鈥檙e researching whether natural language processing techniques such as named entity recognition (automatically finding people, places and organisations in text), regex pattern matching and AI can help address this issue. These techniques will enable a tool that rapidly checks for errors before publication. It鈥檚 designed to work within existing production tools, and we鈥檙e currently working with teams across the 麻豆社 to ensure it meets editorial needs.
麻豆社 style assist
The , a 麻豆社-funded initiative, employs around 150 journalists at regional newspapers around the UK. They supply over 250 stories a day, but many go unused, partly because of the into the 麻豆社 house style. Rewriting typically involves editing for length, structure, flow, and language, and can take around half an hour per article.
The 麻豆社 style guide tool uses AI to redraft articles so they comply with the core style requirements, allowing journalists to focus on refining and polishing the final version. The tool has been through several trials and is now being integrated into 麻豆社 News鈥檚 production tool. We expect it to be available for our journalists to use this year.
麻豆社 News live
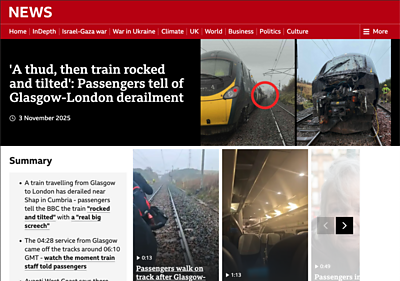
Live news text streams are becoming one of the most popular ways for audiences to engage with 麻豆社 journalism. There are typically more than 25 live events every week across news and the nations and regions, each involving contributions from up to a dozen journalists working in a time-pressured environment. A significant portion of that effort involves manually transcribing TV and radio broadcasts to extract relevant quotes quickly enough for inclusion on the live page.
We鈥檙e working with the news AI team to streamline this process. With accurate transcription and AI-based analysis, we can automate much of the quote-finding and context extraction, provided we can reliably align transcript timings with the output of the large language model (LLM), the audio and other elements. 麻豆社 R&D鈥檚 time addressable media store (TAMS) offers a strong foundation for synchronised, time-linked content retrieval of this type. We have begun a three-month prototype exploring how speech-to-text, AI analysis, and time-aware media infrastructure can help journalists focus more on editorial decisions rather than laborious transcription tasks.
麻豆社 LLM
Commercial large language models are powerful but can be costly to use at scale and often fall short of 麻豆社 style requirements. We鈥檙e developing a fine-tuned model that aligns more closely with 麻豆社 editorial values. It鈥檚 designed to handle time consuming newsroom tasks such as rewriting, headline generation, tagging, and summarisation. Once trained, it can also evaluate outputs from other AI systems for editorial compliance, style adherence, and tone.
We have not built the model from scratch. Instead, we are fine-tuning open-source and open-weight models using 麻豆社 data. To ensure alignment and safety, we鈥檙e combining techniques such as instruction tuning, constitutional alignment and preference learning so 麻豆社 editorial guidelines can be used to directly shape the AI output.
Evaluation work and impact
Building trust in AI means putting evaluation at the centre of how we design, explain and deploy our tools. Over the past year, we鈥檝e developed a mix of machine-based and human evaluation methods to assess accuracy, reliability, and stylistic fit.
In the 麻豆社 style assist project, for example, we worked with journalists in the nations and regions to define clear accuracy measures. We assessed hallucinations, false assertions and misquotations by comparing AI-generated sentences with human-written equivalents. Independent assessors then forensically reviewed the component parts of 2,400 AI-generated sentences to determine whether the source material supported each claim.
Alongside quantitative checks, we developed qualitative style measures around flow, structure, tone, and clarity to judge how well AI outputs match 麻豆社 house style. This also let us test how well our automated metrics predict editorial fit.
However, these measures only matter if they translate into making our colleagues鈥� work easier. So, the bigger picture for our team is always impact, expressed in practical terms such as:
- Minutes saved per article (with no loss of quality).
- Average number of style inconsistencies across 麻豆社 output on a weekly basis.
- Hours saved on transcription, freeing capacity for original journalism.
Collaborate
We collaborate closely with colleagues across the 麻豆社 and also work with world-leading academic groups on our foundational research challenges. These examples are just a small sample of our current work, and we hope to be able to share more with you soon.
If you鈥檙e interested in learning more or exploring a collaboration, please contact us at airesearch.mgmt@bbc.co.uk
Search by Tag:
- Tagged with Artificial Intelligence and Machine Learning Artificial Intelligence and Machine Learning
- Tagged with Journalism Journalism
- Tagged with Content Formats Content Formats
- Tagged with Features Features